

Deploying MLflow on Railway
How I deployed a shared MLflow tracking server with PostgreSQL metadata and external artifacts, then connected JobLab tracing, evaluation, feedback, and prompt optimization to it.
I deployed MLflow because local mlflow ui processes and SQLite files could not provide a stable tracking target for several repositories. The Railway deployment runs the tracking server as a container, stores MLflow metadata in PostgreSQL, and sends artifacts to external object storage.
Deploy the same Railway template.
My JobLab agent uses this server for production request traces, tool spans, evaluation runs, feedback assessments, and prompt-optimization results. The observed deployment was about $20 to $25 per month. That is a snapshot from my services, not a fixed platform price.
Deploy and verify the tracking server
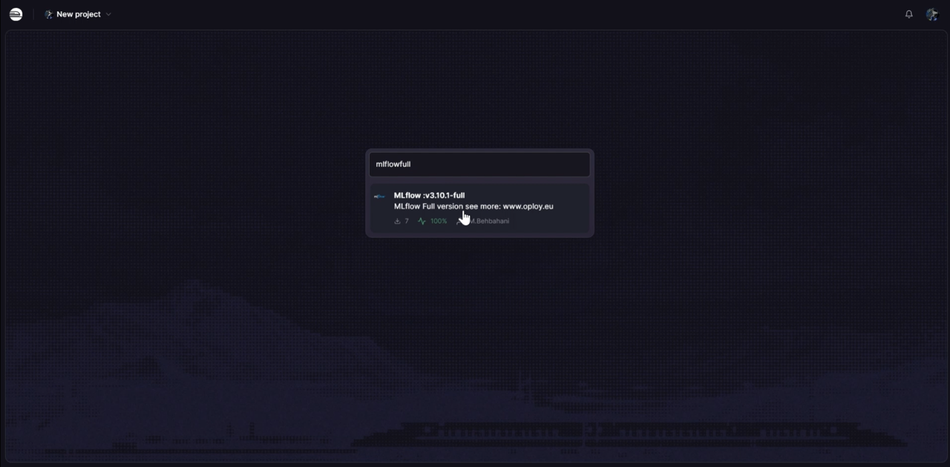
1. Create the services
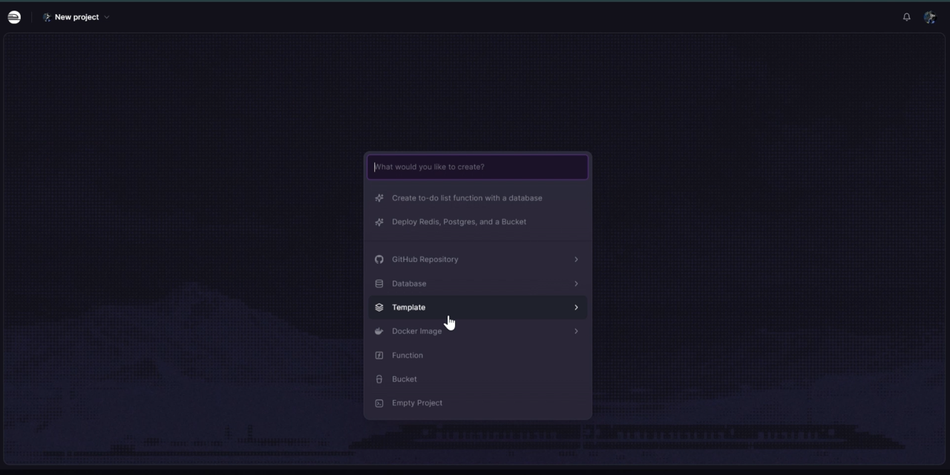
The template creates the MLflow service and its PostgreSQL metadata dependency.
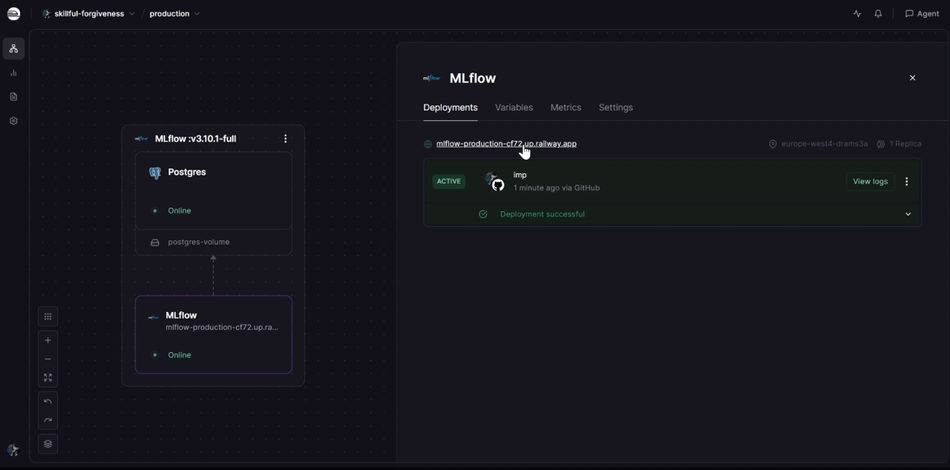
2. Inspect the MLflow container
Confirm the tracking process, database variables, public domain, and restart behavior before connecting an application.
3. Configure clients
MLFLOW_TRACKING_URI=https://your-mlflow-url
The JobLab backend reads this value through its settings layer. Evaluation scripts also call mlflow.set_tracking_uri() explicitly so local runs and production requests resolve to the same server.
4. Verify experiment metadata
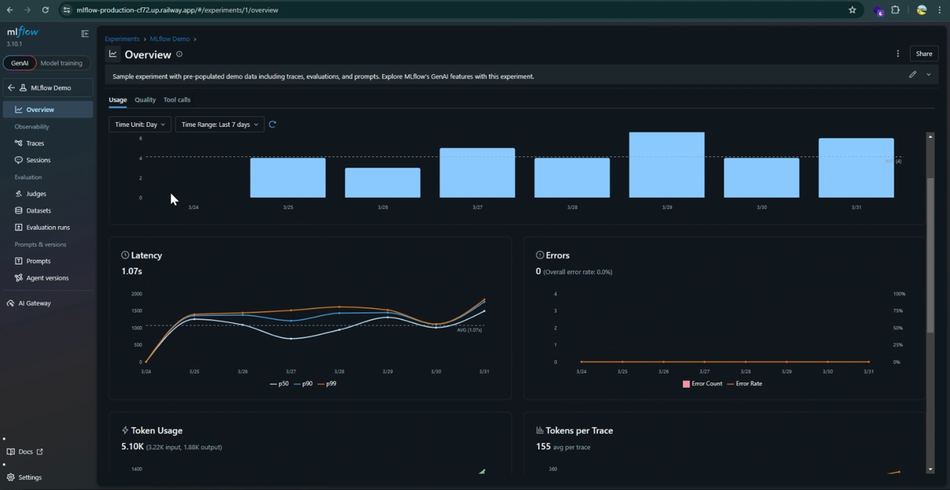
Create a test experiment and run, then confirm parameters, metrics, tags, and artifacts survive a service restart.
5. Verify traces
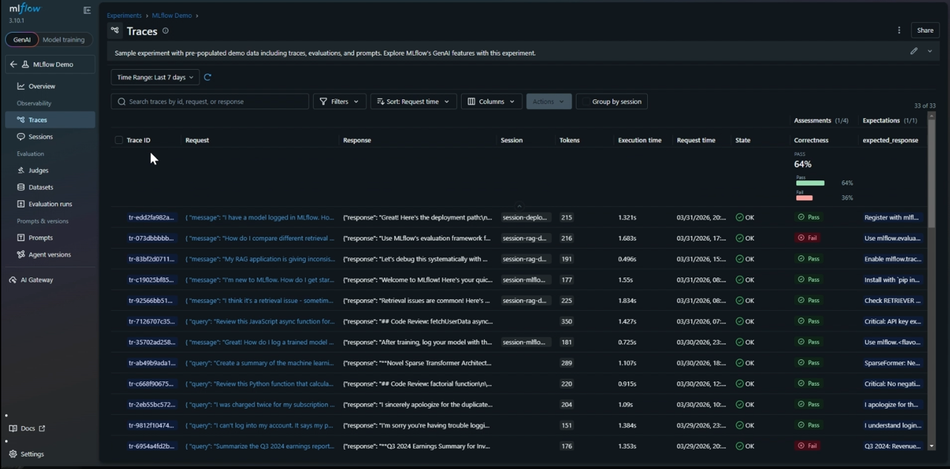
Send one agent request and confirm it creates one root trace with child LLM and tool spans.
6. Inspect span timing
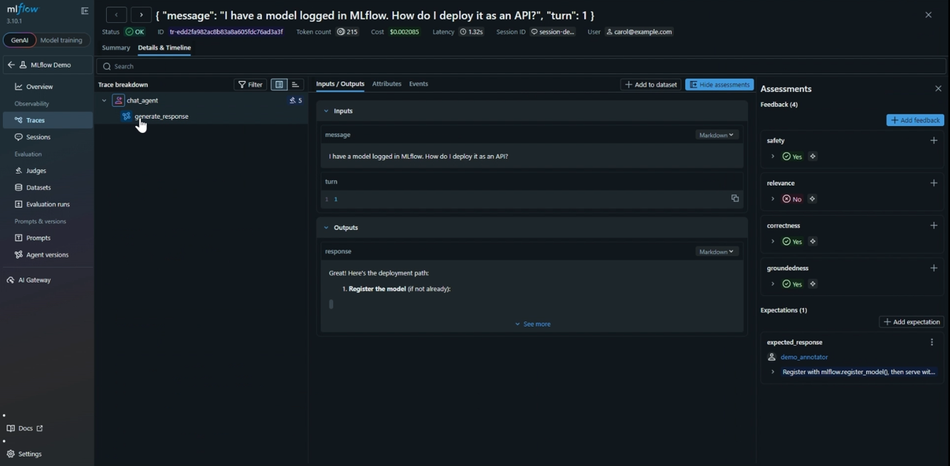
Check tool latency, model latency, retries, and the inputs that produced the response.
Separate metadata from artifacts
The tracking server is stateless enough to restart because PostgreSQL keeps experiment and run metadata. Large files, datasets, and model artifacts belong in object storage. The diagram below shows those responsibilities.
Do not keep durable artifacts only on the Railway container filesystem. Configure external storage with MLFLOW_ARTIFACT_ROOT=s3://your-bucket and scoped AWS credentials. Then test artifact upload and download after restarting the MLflow service.
How JobLab uses the shared server
The agent backend creates request-wide traces in app/routers/ai.py. Tool spans are added in app/services/joblab_tools.py, while app/services/mlflow_lite.py provides a REST fallback and S3-backed spool when the full SDK or tracking server is unavailable.
The evaluation pipeline is kept under MLFLOW_STEPS/: step1_create_experiment.py creates the experiment, step2_register_assets.py registers versioned assets, step3_run_evaluation.py runs the baseline and links backend traces, and step4_optimization.py evaluates prompt candidates. Custom scoring logic lives in evals/mlflow_scorers.py.
The target trace shape is one user question, one root agent trace, and nested model and tool spans. Distributed trace context connects evaluation calls to backend execution so the UI can show the whole path instead of unrelated fragments.
What made this production-useful
Hosting the UI was the easy part. The useful work was persistent metadata, durable artifacts, one-question-one-trace structure, prompt provenance, feedback assessments, distributed context, and a fallback path for tracking outages. Those pieces turned MLflow from a local run viewer into the observability and evaluation layer for the JobLab agent.
Deploy or inspect the setup
- Watch the MLflow deployment walkthrough.
- Deploy the Railway template.
- Read the MLflow documentation.
- Start Railway with $20 in credits if eligible. The referral link does not increase your price.
- Read the FastAPI deployment guide for a smaller application-service example.